Quick Summary
- A web scraper for large-scale data collection automates repetitive research, helping businesses organize accessible web information and reduce manual effort.
- Structured datasets support competitor pricing analysis, market research, and faster decision-making when data quality and collection frequency are managed properly.
- Scalable workflows, APIs, and validation processes help enterprises manage growing data requirements while respecting source permissions, access controls, and applicable regulations.
Introduction
Businesses can reduce manual research costs by automating repetitive data gathering, standardizing records, and delivering structured information directly to analytics workflows. A web scraper for large-scale data collection can help teams replace time-consuming copy-and-paste tasks with repeatable processes, allowing employees to focus on validation, interpretation, and business decisions rather than routine data entry.
Manual research often involves opening multiple websites, locating relevant fields, copying information into spreadsheets, resolving inconsistent formats, and repeating the same work whenever prices or listings change. As the number of products, competitors, or markets grows, this process can become difficult to maintain. Errors and outdated records can also undermine the value of the resulting analysis.
A web data scraper for enterprise analytics is designed around a different operating model: collect permitted information, transform it into a consistent structure, validate the results, and make the dataset available for reporting or downstream systems. Web Scraping Services help businesses streamline this process through structured data collection and automated workflows. Businesses can use this approach for product research, pricing intelligence, supplier discovery, public market information, and other approved data needs.
The business case should be measured rather than assumed. Companies should compare the labor hours, error rates, refresh requirements, infrastructure expenses, and ongoing maintenance costs of manual and automated workflows. Automation may reduce repetitive work, but it does not eliminate the need for monitoring, quality assurance, and source-specific maintenance.
The scale of online commerce helps explain why businesses need organized market intelligence. According to the U.S. Census Bureau, U.S. retail e-commerce sales reached an estimated $340.2 billion in the second quarter of 2026, representing 17.1% of total retail sales on a seasonally adjusted basis. This is a measure of online retail activity, not a measurement of scraping demand or potential cost savings. Source: U.S. Census Bureau, Quarterly Retail E-Commerce Sales.
How can automated competitor research reduce repetitive work?
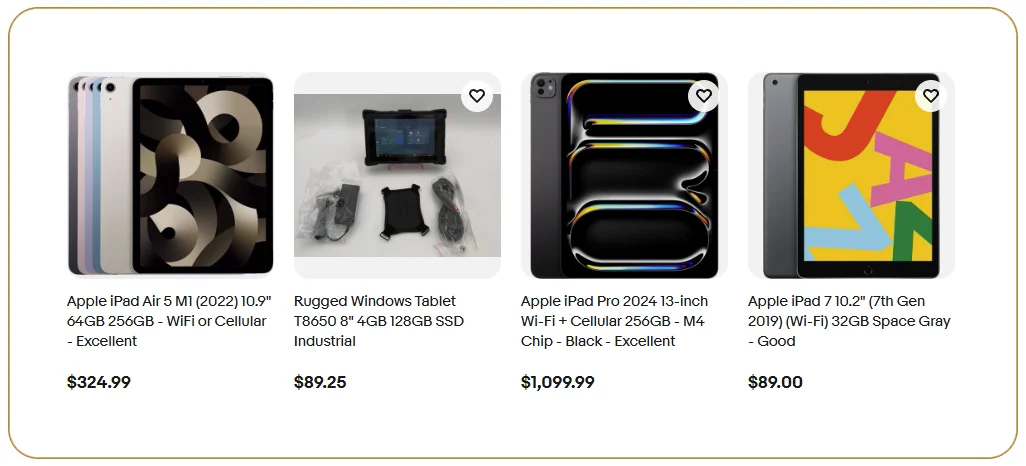
Retail and e-commerce teams often compare product prices, availability, shipping details, and promotional offers across multiple competitors. When these tasks are performed manually, researchers must repeatedly navigate listings, record observations, and reconcile differences between sources. Automation can reduce this repetitive workload when the information is accessible and collection is permitted.
A workflow to scrape competitor pricing data using a web scraper should first identify the exact products and attributes that need comparison. Product names alone are not always sufficient: sizes, pack quantities, product models, delivery locations, and currencies may differ. Reliable matching prevents analysts from treating unlike products as equivalent.
The collection pipeline can then normalize the captured values and retain the observation time. Analysts can compare current and previous prices, flag unusual changes, and route exceptions to category managers rather than reviewing every record manually. This approach is especially useful when the same research must be repeated across many products or locations.
The scale of online retail provides context for this need. The table below shows the U.S. e-commerce share of total retail sales at selected year-end observations, followed by the latest available second-quarter observation for 2026.
| Observation period | E-commerce share of U.S. retail sales |
|---|---|
| Q4 2020 | 15.0% |
| Q4 2021 | 14.6% |
| Q4 2022 | 14.6% |
| Q4 2023 | 15.5% |
| Q4 2024 | 16.2% |
| Q4 2025 | 16.7% |
| Q2 2026 | 17.1% |
Source: U.S. Census Bureau e-commerce series via FRED. The 2020–2025 values are fourth-quarter observations; 2026 is the second quarter, so the periods are not directly equivalent.
These figures demonstrate the importance of online retail as a sales channel, but they do not prove any specific productivity gain from scraping. Businesses should measure their own baseline research hours, cost per usable record, and error rate before estimating savings.
What should businesses expect from an API-driven monitoring workflow?
An API-driven collection workflow provides a defined interface for requesting data and receiving structured responses. Instead of building every downstream process around manually exported files, businesses can integrate approved data sources with databases, analytics platforms, and internal applications.
A web scraper API for competitor price monitoring can support scheduled requests, consistent field structures, and integration with existing business systems, depending on the provider's capabilities and source permissions. The design should specify the data fields, refresh cadence, response format, error-handling rules, and usage limits before production deployment.
A practical implementation typically includes:
- Request management: Submit permitted requests according to the source's rules and the service's documented limits.
- Response parsing: Convert available information into defined fields such as product identifier, displayed price, currency, and timestamp.
- Validation: Check for missing values, unexpected formats, duplicates, and product-matching errors.
- Storage: Preserve historical observations rather than replacing prior records without traceability.
- Monitoring: Track failed requests, response changes, and data freshness so teams can investigate gaps.
The financial benefit depends on the amount of repetitive work removed and the cost of operating the new system. A business should calculate the total cost of ownership, including API usage, infrastructure, engineering, maintenance, and quality checks. An automated workflow may be less expensive at scale, but it is not automatically cheaper for every use case.
It is also important to distinguish an API that delivers existing data from a service that collects information from websites. Access methods, available fields, and permissions can vary. An integration should not be described as real-time unless its documented refresh behavior and source availability support that claim.
For decision-makers, the most useful success measures are cost per validated record, time from source change to usable insight, data completeness, and the number of manual steps eliminated.
How does faster market research support better decisions?
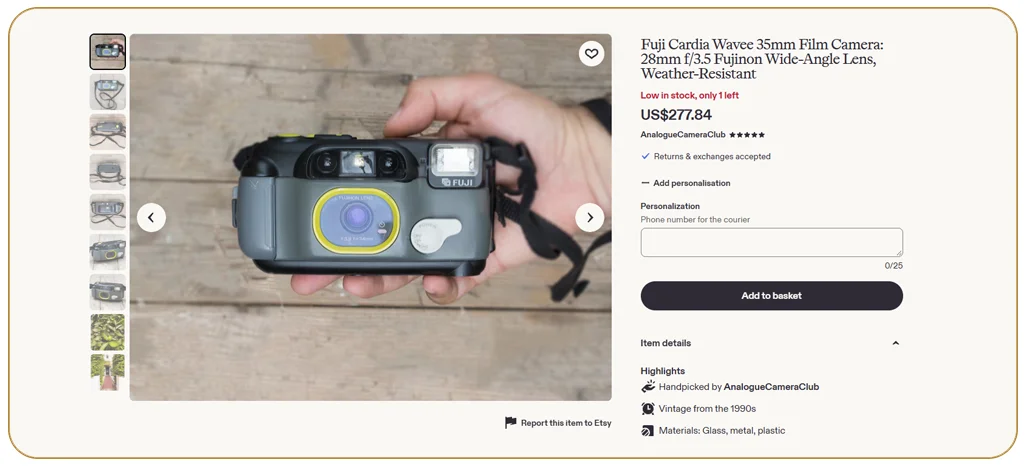
Market research loses value when observations arrive after the business decision has already been made. Product launches, pricing reviews, assortment planning, and campaign analysis can all benefit from timely information, provided the collected records are accurate and relevant to the decision.
Real-time web data collection for market research describes a workflow designed to make observations available with minimal delay. However, "real-time" should be defined carefully. Some sources update continuously, while others publish changes periodically or limit access. The actual freshness of the dataset depends on source behavior, permitted access, processing time, and delivery architecture.
Teams should begin by classifying their information needs. Competitor price monitoring may require frequent updates for selected products, while broad category research may only need daily or weekly snapshots. Matching the collection cadence to the business question avoids paying for unnecessary refreshes.
A useful research dataset should include source references, observation timestamps, normalized categories, and data-quality indicators. These details help analysts distinguish a genuine market change from an extraction failure or a mismatch between products.
Before deployment, establish measurable objectives:
- Record the time and labor required by the current manual process.
- Define the required fields and acceptable data-completeness threshold.
- Agree on how quickly a new observation must become available.
- Measure failed records and the time spent correcting them.
- Review total operating costs after the workflow has run long enough to assess maintenance needs.
Faster information does not guarantee better decisions. Analysts still need context, appropriate comparisons, and internal business metrics. For example, a competitor's lower price may not justify a price reduction if the products differ in quality, delivery terms, or profitability.
Need to make research more repeatable? Define your priority data sources, target fields, and refresh requirements before choosing a collection architecture. This helps align the solution with business value rather than collecting large amounts of information that teams cannot use.
How can a scalable architecture handle increasing data volumes?
A data collection system that works for a small project may struggle when the number of sources, products, or scheduled jobs increases. Scalability requires more than sending additional requests. It also involves managing concurrency, handling failures, limiting duplicate work, validating outputs, and storing historical records efficiently.
Mastering Scalability Building Web Scrapers with Scrapy involves designing a crawl process around clear rules and measurable limits. Scrapy's official documentation describes its AutoThrottle extension, which adjusts download delays based on response latency and configured concurrency. The extension also respects settings such as per-domain concurrency and minimum download delay. These controls help developers manage request rates rather than sending requests as quickly as possible. Source: Scrapy AutoThrottle documentation.
A scalable architecture can include separate components for job scheduling, permitted data retrieval, parsing, validation, storage, and delivery. Separating these responsibilities helps teams identify where delays or failures occur. Queues can distribute work, while retries and checkpoints can help recover from transient failures without restarting an entire collection run.
The following design practices are particularly useful:
- Set source-specific limits: Avoid assuming that every website supports the same request rate or access method.
- Use incremental collection: Where permitted and technically supported, prioritize changed records instead of reprocessing everything.
- Build idempotent processing: Reprocessing the same input should not unintentionally create duplicate business records.
- Monitor pipeline health: Track success rates, response times, completeness, and processing delays.
- Plan for schema changes: Validate unexpected response structures before they affect downstream reporting.
Scrapy is an open-source framework, not a guarantee that any particular website can be accessed or scraped. Source restrictions, authentication requirements, anti-automation controls, and applicable laws still determine what can be collected.
The right architecture balances throughput, reliability, cost, and responsible access. Its success should be evaluated through measured performance and data quality—not simply the number of requests sent.
What makes enterprise data collection dependable?
Large organizations often need the same information to serve several teams. Pricing analysts may need historical comparisons, procurement teams may need supplier details, and executives may need high-level market indicators. If each team maintains a separate collection process, inconsistent definitions and duplicated effort can emerge.
Enterprise Web Scraping should therefore be treated as a managed data workflow rather than a collection of isolated scripts. The design should establish ownership, permissions, standardized schemas, quality controls, monitoring, and documented delivery expectations.
A dependable workflow should address five areas:
| Area | Recommended control | Business value |
|---|---|---|
| Governance | Document source permissions, permitted use, and data ownership | Reduces compliance uncertainty |
| Data quality | Validate fields, types, timestamps, and product matches | Improves analytical reliability |
| Operations | Monitor failures, delays, and schema changes | Makes issues easier to detect |
| Security | Apply least-privilege access and protect credentials | Limits unnecessary access |
| Delivery | Define schemas, refresh schedules, and service expectations | Helps downstream teams plan |
Cost control requires the same discipline. Teams should track infrastructure use, provider charges, engineering hours, support effort, and the cost of correcting poor-quality data. A low-cost extraction process can become expensive if it produces records that need extensive manual repair.
Enterprises should also distinguish public business information from personal or sensitive information. Data minimization, access controls, retention rules, and source-specific restrictions should be considered at the design stage. Public availability does not automatically authorize every collection or reuse scenario.
For executives, the goal is not to maximize the volume of collected information. It is to maintain a trusted supply of relevant data that supports measurable business outcomes. A smaller, validated dataset may be more valuable than a much larger collection with uncertain provenance or inconsistent fields.
How can an API make collected information easier to use?
An API can provide a consistent way for applications to request, receive, and process data. For research and analytics teams, this can reduce the need to move files manually between systems and help standardize how data enters internal workflows.
A Web Scraping API may offer structured responses, request parameters, documented limits, and defined error responses. Specific features differ by provider, so businesses should verify supported sources, returned fields, authentication methods, rate limits, refresh behavior, and data-retention arrangements before selecting a service.
An API integration project should define the expected request and response schema first. For example, product-monitoring workflows may require an item identifier, price, currency, availability, source reference, and timestamp. Fields that the source does not expose should remain unavailable rather than being inferred without evidence.
Teams should also plan for operational exceptions. An API may return an error, a source may change its page structure, or an observation may be incomplete. Validation rules and error handling should prevent these conditions from silently contaminating reports.
A sound implementation checklist includes:
- Confirm source authorization and provider terms.
- Test the schema against representative, permitted responses.
- Establish timeouts, retry policies, and usage limits.
- Store source timestamps and collection timestamps separately where relevant.
- Monitor completeness, freshness, and failed requests.
- Document changes that could affect downstream applications.
API-based delivery is particularly helpful when multiple internal tools need the same validated dataset. However, an API does not automatically make source collection instant, comprehensive, or maintenance-free. Its value depends on the quality of the underlying data and the reliability of the delivery process.
Businesses should pilot the workflow on a defined set of sources, measure its operating costs, and confirm that it meets data-quality requirements before expanding coverage.
Why choose Real Data API?
Choosing the right data collection partner requires evaluating source coverage, reliability, data structure, operational support, and compliance requirements. Real Data API can be considered as part of a data strategy focused on delivering structured information for business research and analytics, subject to the service capabilities and source permissions confirmed for the project.
A web scraper for large-scale data collection should be selected based on the business problem it solves, not simply the volume of records it can retrieve. Buyers should assess whether the solution supports their required sources, fields, delivery format, refresh frequency, and data-quality expectations.
Key evaluation criteria include:
- Business alignment: Does the proposed workflow address a defined research or operational problem?
- Data quality: Are records validated, consistently structured, and traceable to their sources?
- Scalability: Can the workflow expand while maintaining acceptable cost and performance?
- Integration: Can the output connect to existing databases, dashboards, or analytics systems?
- Transparency: Are access permissions, service limitations, and data freshness clearly documented?
- Cost management: Can the business measure total operating costs against the manual process it replaces?
Before committing to a large deployment, businesses should agree on a pilot scope and measurable success criteria. These might include cost per validated record, time saved per research cycle, completeness, and delivery reliability. This approach gives decision-makers a practical basis for assessing whether the solution provides sustainable value.
Ready to make your data collection more efficient? Contact Real Data API to discuss your requirements, explore suitable data access options, and plan a scalable workflow aligned with your business goals!
Conclusion
Automating repetitive research can help businesses reduce manual effort, standardize information, and make market intelligence easier to maintain. The strongest results come from combining an appropriate collection architecture with clear source permissions, structured data, quality checks, and measurable cost controls.
A web scraper for large-scale data collection can support competitor analysis, market research, and enterprise reporting when it is designed around real business needs. Businesses should evaluate the complete workflow—from permitted source access and data validation to storage, integration, and ongoing maintenance—before estimating savings.
Ready to make your data collection more efficient? Contact Real Data API to discuss your requirements, explore suitable data access options, and plan a scalable workflow aligned with your business goals!
Frequently asked questions
1. How does a web scraper for large-scale data collection reduce costs?
A web scraper for large-scale data collection automates repetitive retrieval and formatting tasks, reducing manual handling. Actual savings depend on infrastructure, maintenance, source access, and validation costs.
2. When should businesses choose Web Scraping Services?
Web Scraping Services suit businesses that need recurring, structured information from permitted sources. Evaluate data quality, source coverage, refresh schedules, integration options, and total operating costs before choosing a provider.
3. What is a web data scraper for enterprise analytics?
A web data scraper for enterprise analytics gathers permitted online information and organizes it for reporting, benchmarking, and decision-making. Reliable workflows include validation, source tracking, and consistent schemas.
4. Can businesses scrape competitor pricing data using a web scraper?
Businesses can scrape competitor pricing data using a web scraper only when the collection method is permitted. Accurate product matching, timestamps, and currency normalization improve comparison quality.
5. What does a web scraper API for competitor price monitoring provide?
A web scraper API for competitor price monitoring can deliver structured observations to business systems. Real Data API capabilities should be confirmed against required sources, fields, access permissions, and refresh expectations.
Latest posts
Used & Rental Car Price Scraping: Turo, Kayak, Priceline & mobile.de Vehicle Listings
Marketplace Seller Data Scraping: Walmart, TikTok Shop, Etsy & Amazon Category Data
BookMyShow Data Scraping: Movie-Wise & City-Wise Ticket Availability and Pricing
India Medicine Database Scraping: 1mg, PharmEasy & Netmeds (Brands, Salts, MRP)


.png)


