.webp)
Quick Summary
- Businesses can turn publicly available Reddit conversations into structured datasets using a Reddit Scraper for consumer research, trend discovery, product intelligence, and competitive analysis.
- The Reddit Social Media Dataset helps research teams monitor changing discussions, identify recurring themes, compare market sentiment, and build historical datasets without relying on manual browsing.
Introduction
Businesses can collect public Reddit content to understand customer opinions, emerging trends, product discussions, and competitive signals. A Reddit Scraper can organize publicly accessible posts, comments, timestamps, subreddit information, engagement signals, and other permitted fields into structured datasets for analysis.
Reddit has become an important source of community-driven discussions across technology, finance, travel, gaming, healthcare, consumer products, and thousands of niche interests. For research teams, Reddit Social Media Dataset creation provides a way to transform scattered conversations into searchable information. The key is to collect only data that is publicly accessible and to follow Reddit's applicable terms, API requirements, privacy rules, and usage restrictions.
What is Reddit web scraping for market research?
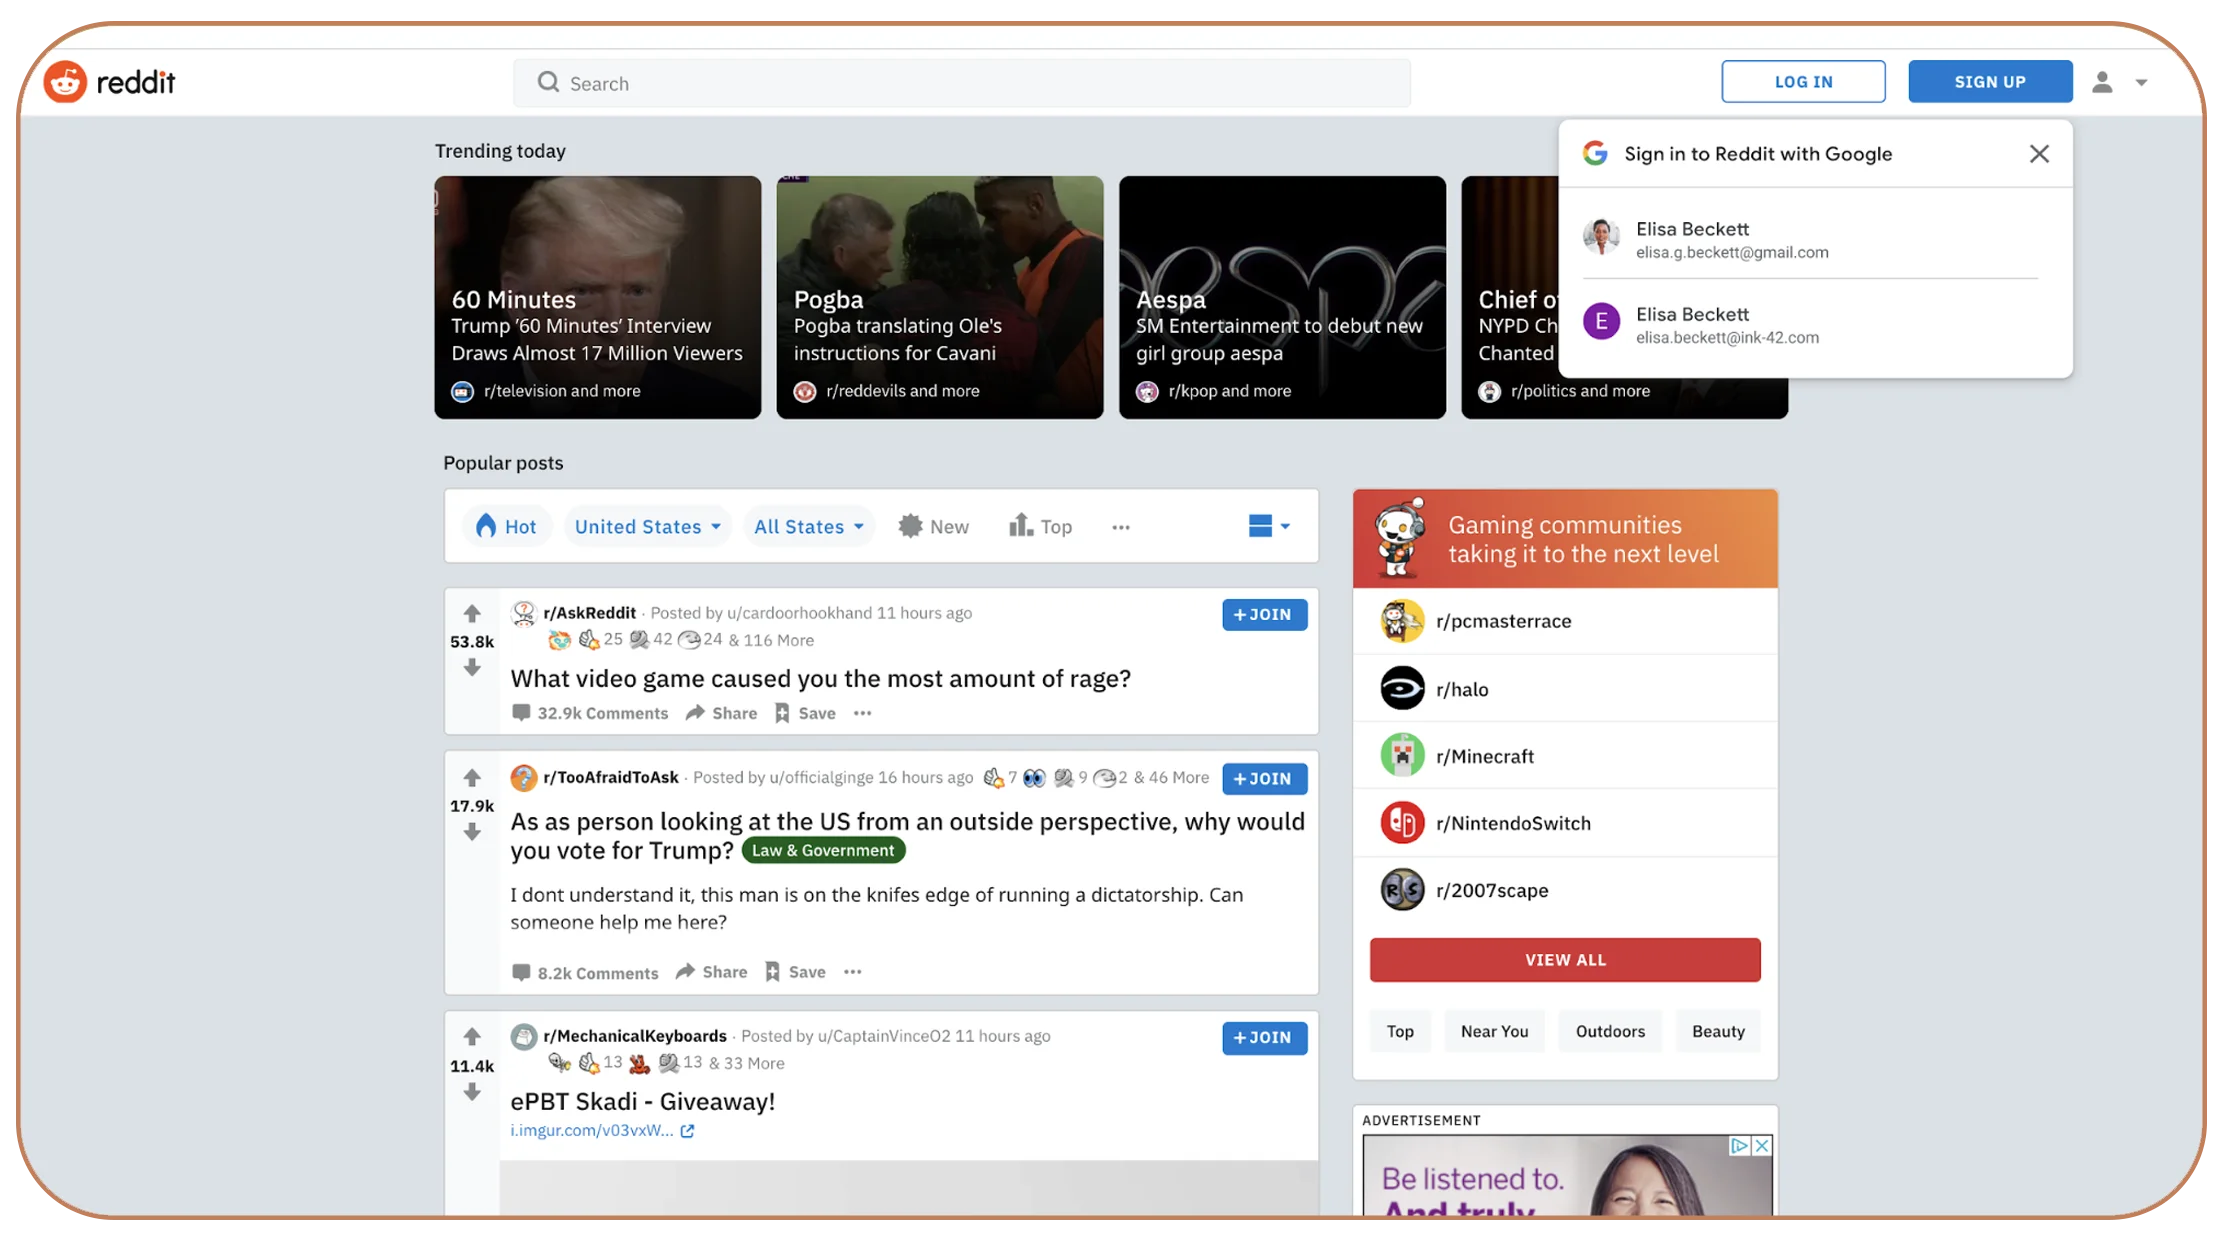
Reddit web scraping for market research involves systematically collecting publicly available Reddit information and organizing it for research purposes. Instead of manually reading individual threads, businesses can create structured datasets that help identify recurring questions, product complaints, emerging interests, customer preferences, and competitor discussions.
For a market researcher, the value comes from scale and historical context. A single Reddit thread may provide anecdotal insight, while thousands of relevant posts can reveal recurring patterns that deserve deeper investigation.
How Can Businesses Capture Changing Conversations?
Reddit real-time social media data can help businesses monitor fast-moving discussions and detect changes in public conversations. Depending on the collection method, teams can track newly published posts, comments, engagement activity, subreddit discussions, and selected topics at defined intervals.
This capability is particularly useful for businesses operating in markets where consumer preferences change quickly. A brand launching a product, for example, can monitor relevant communities to identify questions, complaints, reactions, and feature requests. A financial research team can observe discussions around specific sectors or themes. A technology company can analyze conversations around competing products.
| Monitoring Area | Example Metric | Business Use |
|---|---|---|
| New posts | 1,000+ monthly | Identify emerging topics |
| Comments | 5,000+ monthly | Analyze detailed opinions |
| Engagement | Upvotes/comments | Prioritize influential discussions |
| Subreddits | 20+ communities | Compare audience segments |
| Keywords | 100+ terms | Track specific themes |
The figures above are illustrative dataset-planning examples, not Reddit-wide statistics.
From 2020 through 2022, online community discussions became increasingly valuable for understanding consumer behavior as digital engagement expanded. In 2023, Reddit's API changes became a major consideration for organizations collecting platform data. Reddit announced updated Data API terms and introduced premium access for use cases requiring higher limits and broader rights.
In 2024, Reddit reported 101.7 million daily active uniques for the fourth quarter, up 39% year over year. In 2025, the platform reported 121.4 million daily active uniques for Q4, representing 19% year-over-year growth. These figures demonstrate why public discussions can represent a substantial research signal.
By 2026, organizations should treat freshness, compliance, source validation, and collection frequency as core parts of their data strategy. Reddit's developer ecosystem is also evolving, with Reddit directing developers toward its Developer Platform and announcing changes to public API access.
Turn Reddit conversations into structured research data with a scalable collection strategy.
What Makes an API-Based Collection Approach Useful?
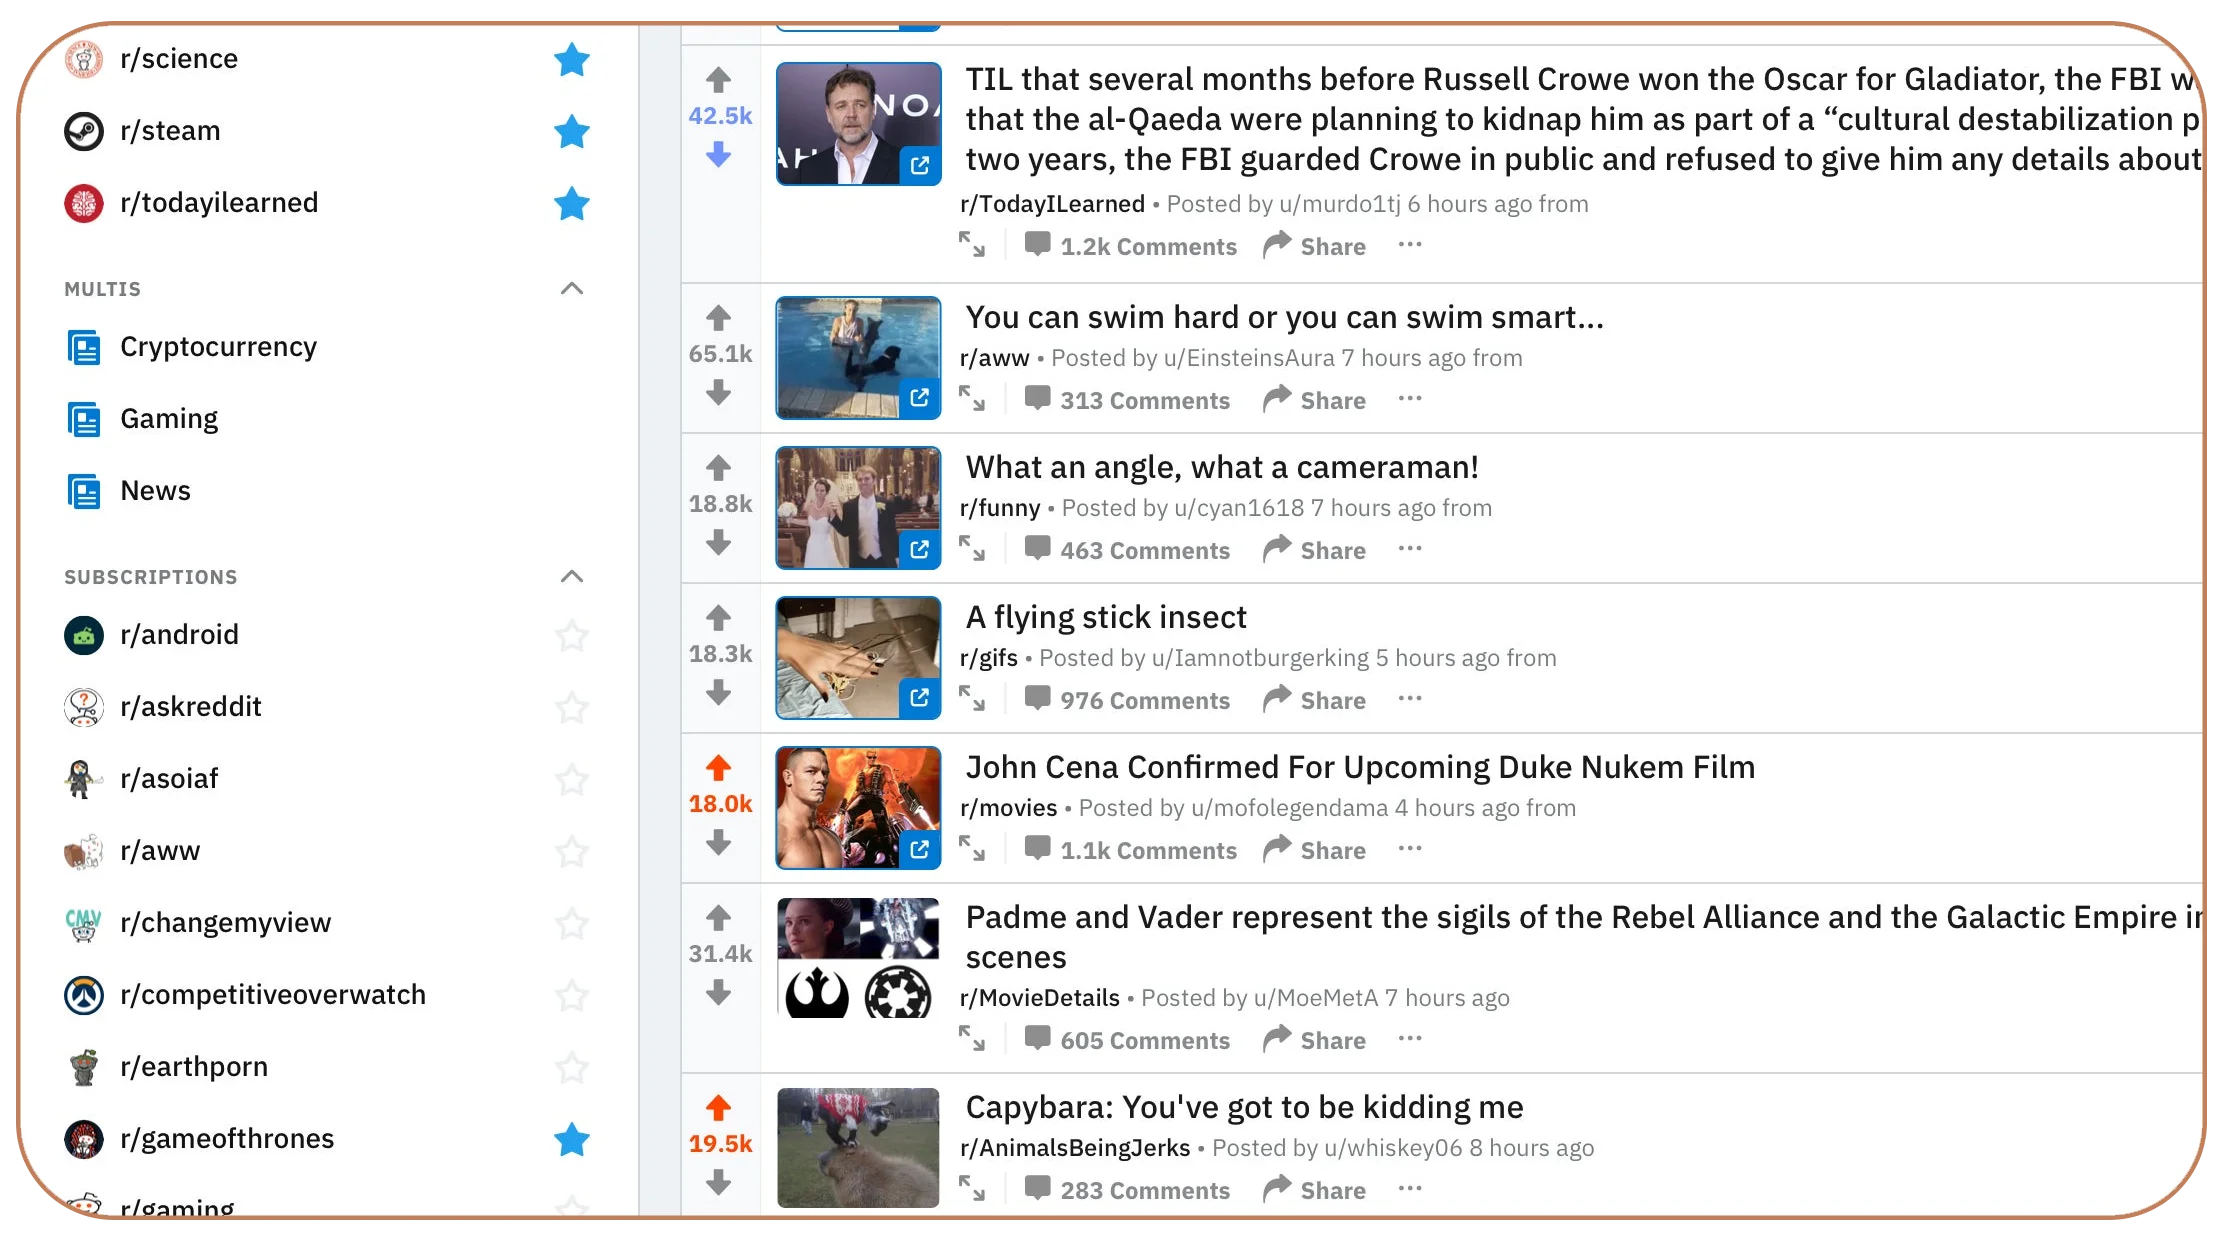
A Reddit data extraction API can provide a structured way to retrieve permitted Reddit information without requiring researchers to manually navigate thousands of pages. API-based workflows can simplify authentication, pagination, data retrieval, filtering, and downstream processing when the selected access method supports the required use case.
Reddit's documentation describes listing mechanisms using parameters such as after, before, limit, and count, enabling applications to work through changing collections of content.
For businesses, the primary advantage is consistency. Instead of creating one-off research exports, teams can establish recurring data pipelines that normalize fields into a common schema.
| Stage | Activity | Output |
|---|---|---|
| 1 | Source selection | Relevant subreddits |
| 2 | Query configuration | Keywords/topics |
| 3 | Retrieval | Posts/comments |
| 4 | Pagination | Expanded records |
| 5 | Validation | Clean records |
| 6 | Storage | Historical dataset |
| 7 | Analysis | Research insights |
The 2020–2022 period highlighted the importance of scalable digital research as organizations increasingly depended on online signals. By 2023, Reddit's API policy and pricing changes demonstrated that platform access cannot be treated as static infrastructure. Developers and businesses needed to review applicable access rules and technical requirements.
In 2024, structured collection became increasingly relevant as Reddit's user activity expanded. Reddit's reported 101.7 million Q4 daily active uniques provided an indication of the platform's scale.
In 2025, Reddit reached 121.4 million Q4 daily active uniques, reinforcing the potential research value of large-scale community conversations.
In 2026, teams should evaluate whether their workflow should use Reddit's current API capabilities, Developer Platform options, or another permitted collection method. Reddit states that its Developer Platform is now the primary route for developing Reddit extensions and offers functionality beyond older public API approaches.
The best architecture depends on the buyer's requirements, collection frequency, fields required, historical depth, compliance constraints, and intended analytical application.
How Can Companies Collect Public Reddit Information at Scale?
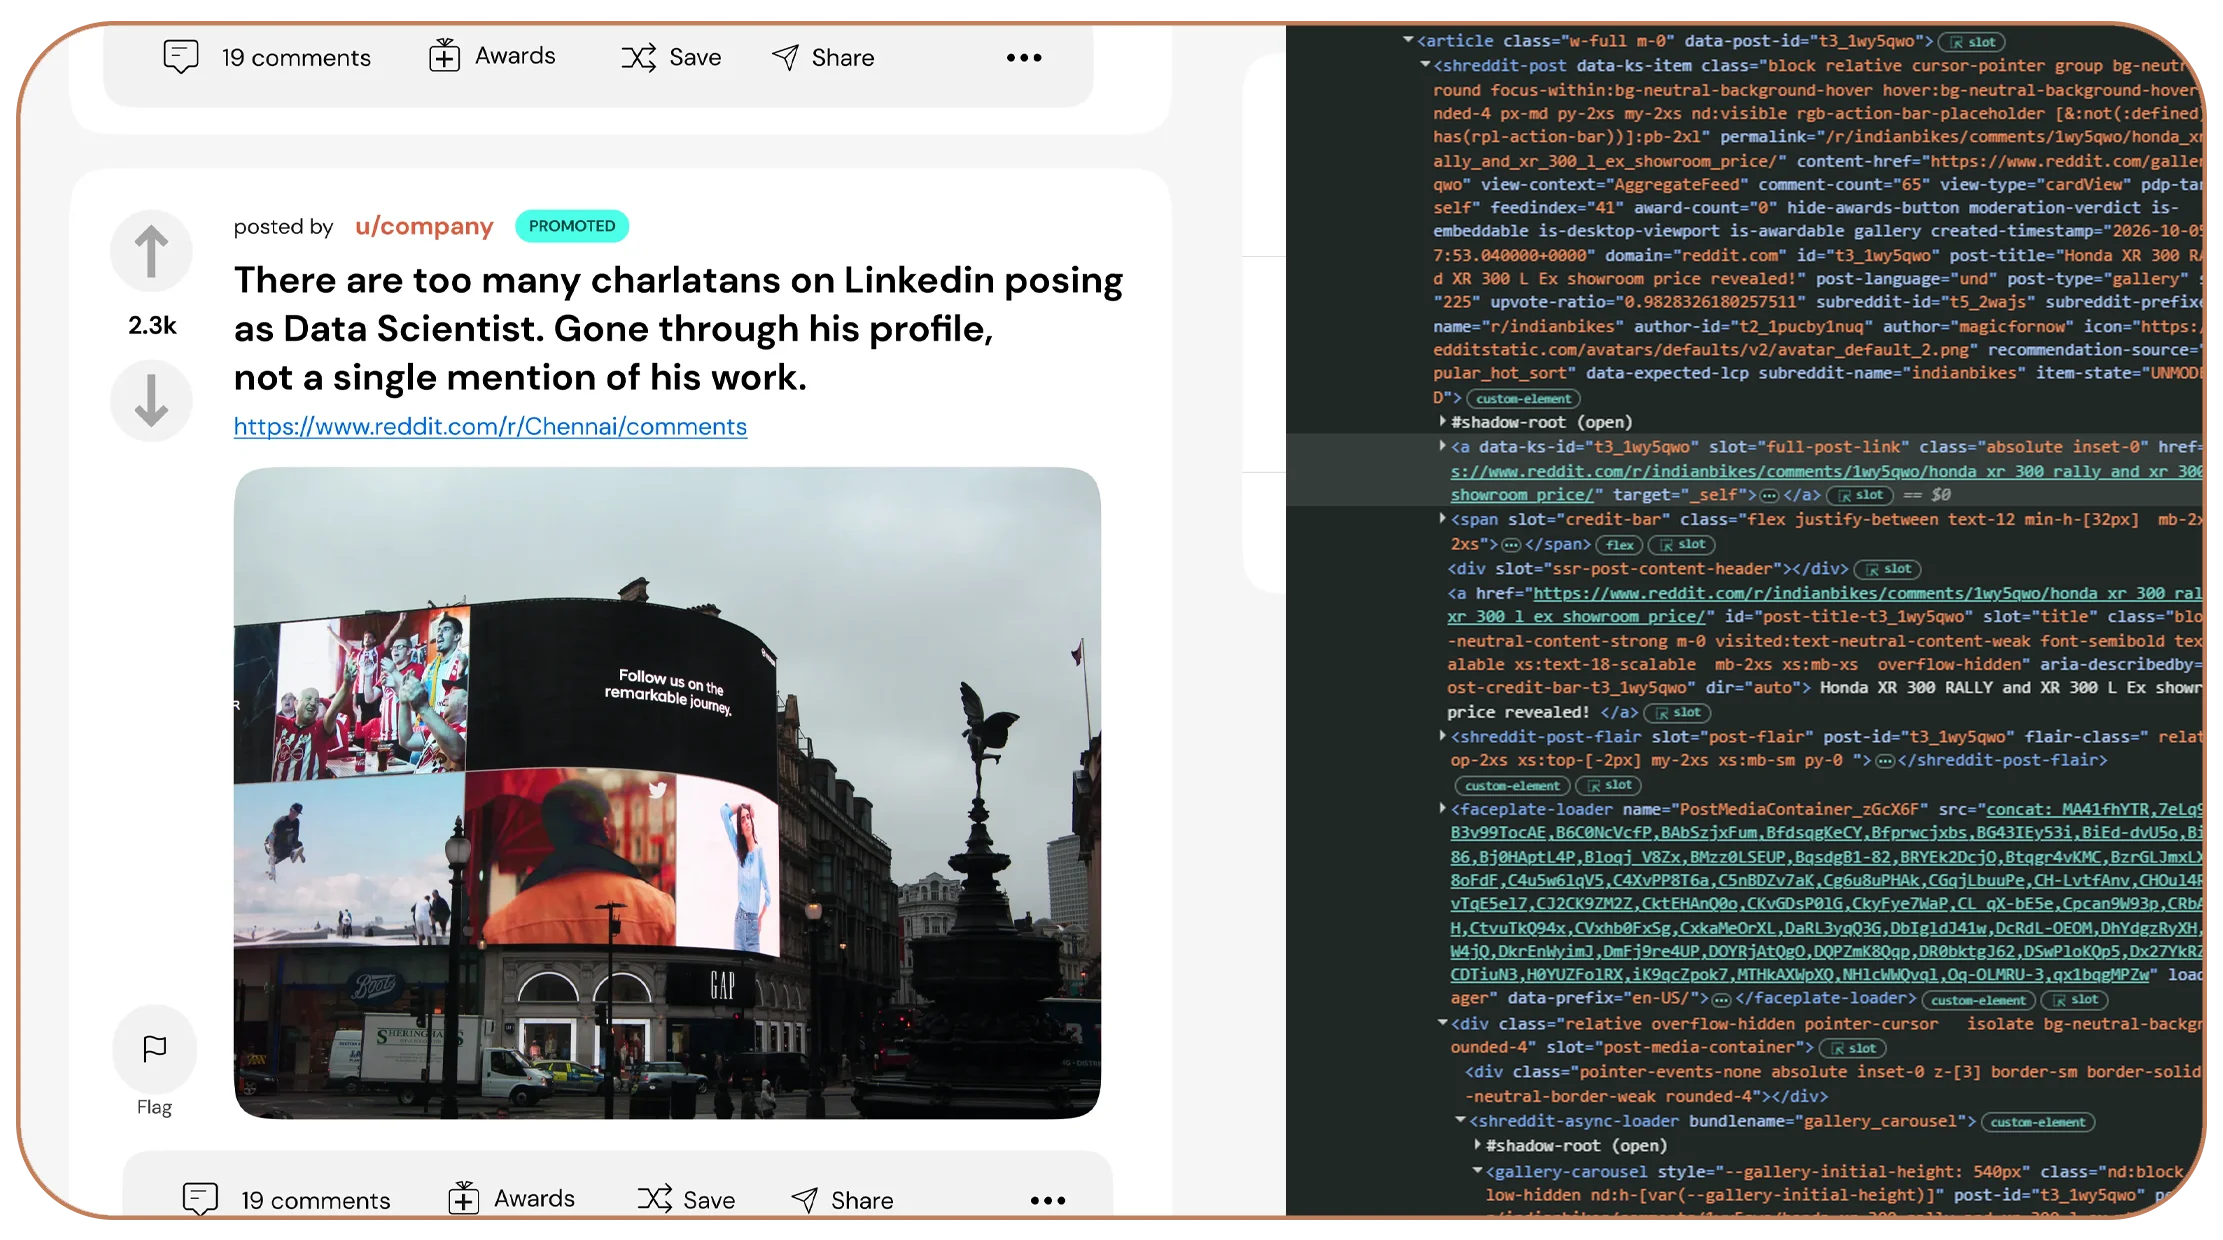
Businesses can extract public data from Reddit by defining relevant communities, keywords, time periods, and fields before building a structured collection workflow. The objective should not simply be to gather as much information as possible. Effective research depends on collecting the right information at the right frequency.
For example, a consumer electronics company may monitor discussions around competing devices, recurring product complaints, feature requests, and purchasing questions. A research agency may track category-specific discussions across dozens of communities.
| Field | Purpose |
|---|---|
| Post ID | Unique record identification |
| Subreddit | Community segmentation |
| Post title | Topic classification |
| Post text | Content analysis |
| Comment text | Opinion analysis |
| Timestamp | Historical tracking |
| Score | Engagement measurement |
| Comment count | Discussion depth |
| URL | Source reference |
| Topic tag | Research categorization |
From 2020 to 2022, organizations increasingly adopted digital listening methods to supplement conventional surveys and interviews. The benefit was access to naturally occurring discussions rather than responses generated only after a researcher asked a question.
During 2023, platform-access changes made compliance and collection architecture more important. Reddit's announced Data API changes included updated terms and a premium access model for certain third-party use cases.
During 2024 and 2025, Reddit's growing daily active audience increased the potential volume of publicly visible conversations available for research, while also making efficient filtering more important. Reddit reported 101.7 million Q4 2024 DAUq and 121.4 million Q4 2025 DAUq.
In 2026, research teams should combine source selection, data minimization, validation, deduplication, historical storage, and semantic analysis. This produces more useful datasets than indiscriminate collection.
Build a focused public-data pipeline around the Reddit communities and topics that matter to your business!
Get Insights Now!How Does a Reddit Scraper Support Business Research?
A Reddit Scraper can automate repetitive collection tasks and convert relevant public discussions into structured records. For business users, the objective is usually not scraping for its own sake. The real objective is creating a reliable information layer that supports market research, consumer intelligence, product development, competitive monitoring, or trend analysis.
Where can it help?
- Consumer research: Identify recurring customer questions and opinions.
- Product intelligence: Discover feature requests and product complaints.
- Competitive research: Track discussions around competing brands.
- Trend monitoring: Detect topics gaining attention.
- Content strategy: Discover questions that audiences repeatedly ask.
- Reputation monitoring: Identify recurring positive or negative themes.
- Category research: Compare discussions across communities.
A scalable architecture can include source discovery, request management, extraction, validation, deduplication, storage, enrichment, and analytics.
| Workflow Stage | Example Output |
|---|---|
| Discovery | 50 relevant communities |
| Filtering | 200 target terms |
| Collection | Posts and comments |
| Cleaning | Standardized records |
| Classification | Topic and sentiment tags |
| Storage | Historical database |
| Reporting | Dashboard and exports |
The approach evolved significantly between 2020 and 2026. Early workflows often relied on relatively simple scripts and scheduled jobs. As data volumes grew, organizations began requiring stronger orchestration, validation, historical storage, and monitoring.
The 2023 API transition was especially important because collection strategies had to account for updated access rules and usage requirements.
By 2025, Reddit's Q4 DAUq had reached 121.4 million. In 2026, Reddit is further changing its developer ecosystem and has announced registration and migration requirements for certain existing API applications.
For buyers, this means technical capability should be paired with compliance awareness, source validation, and a clear business objective.
What Can Structured Social Data Reveal?
Social Media Datasets can turn unstructured conversations into information that analysts can filter, compare, classify, and visualize. Their value increases when the dataset has consistent fields, reliable timestamps, clear source references, and a defined analytical purpose.
A business may create separate datasets for product reviews, competitor discussions, customer questions, emerging trends, or category conversations.
| Dataset Layer | Example Information |
|---|---|
| Identity | Post/comment ID |
| Source | Subreddit |
| Content | Text/title |
| Time | Publication timestamp |
| Engagement | Score/comments |
| Classification | Topic/category |
| Sentiment | Positive/neutral/negative |
| Entity | Brand/product |
| Geography | Location references |
| Research tag | Custom business label |
Between 2020 and 2022, many research workflows focused on gathering broad conversation data. From 2023 onward, the emphasis increasingly shifted toward controlled access, structured collection, and better analytical quality.
The platform's scale continued to grow. Reddit reported 101.7 million daily active uniques in Q4 2024 and 121.4 million in Q4 2025. For research teams, this growth increases both opportunity and the need for effective filtering.
A useful dataset should answer a specific business question. For example, instead of collecting every post mentioning "smartphone," a company could collect posts discussing camera quality, battery life, upgrade intent, or competing models within selected communities.
In 2026, AI-assisted classification can further improve research workflows by grouping similar discussions, extracting entities, summarizing recurring themes, and identifying changes over time. However, automated interpretation should be validated against the underlying source records.
The strongest approach combines structured collection with human-defined research questions.
Can Python Automate Reddit Data Collection?
Businesses can Scrape Reddit in Python for research workflows when the selected method, source, and use case comply with Reddit's applicable requirements. Python is popular because it supports HTTP requests, JSON processing, data transformation, storage, scheduling, and analytics through a broad ecosystem of libraries.
| Component | Purpose |
|---|---|
| Request layer | Retrieve permitted content |
| Parser | Process returned data |
| Validator | Check required fields |
| Transformer | Normalize records |
| Database | Store historical information |
| Scheduler | Run recurring jobs |
| Analytics | Calculate research metrics |
| Dashboard | Present findings |
From 2020 through 2022, Python-based research scripts were commonly used for small and medium-scale data projects. By 2023, API policy changes made authentication, rate limits, permitted usage, and platform terms critical considerations. Reddit's documentation continues to emphasize its API access rules.
In 2024 and 2025, increasing platform activity created greater demand for filtering and efficient data handling. Reddit's reported growth from 101.7 million Q4 2024 DAUq to 121.4 million Q4 2025 DAUq illustrates the scale that modern research infrastructure may need to accommodate.
In 2026, Python remains useful as part of a broader architecture rather than as the entire solution. Production systems may require queue management, storage, monitoring, retry logic, data-quality checks, analytics pipelines, and access controls.
The practical lesson is simple: Python can provide the engineering layer, but successful market research depends on source selection, data quality, analytical design, and responsible collection.
Why Choose Real Data API?
For organizations that need structured web and social data without building every component internally, Reddit Scraper solutions can reduce the technical workload involved in collection, normalization, and delivery.
Real Data API can support businesses that need repeatable datasets for market research, competitor intelligence, consumer research, product analysis, and trend monitoring. The value is not simply the volume of records collected. A useful solution should provide consistent fields, reliable refreshes, clean outputs, and formats that analysts can immediately use.
Key advantages
- Scalable collection: Designed for recurring data requirements.
- Structured output: Converts raw information into analysis-ready records.
- Custom fields: Supports business-specific research requirements.
- Historical tracking: Enables comparison across collection periods.
- Data quality: Validation and normalization improve analytical consistency.
- Flexible delivery: Data can be prepared for databases, dashboards, or analytical workflows.
- Business focus: Collection is aligned with specific research objectives rather than indiscriminate data gathering.
For buyers, the right provider should also demonstrate awareness of platform policies and changing access requirements. Reddit's current developer documentation highlights the move toward its Developer Platform, while public API access and registration requirements are evolving.
Conclusion
A Reddit Scraper can help businesses transform publicly accessible conversations into structured market intelligence. When designed around specific research questions, it can support consumer research, product intelligence, competitive analysis, trend discovery, and content planning.
Reddit's audience scale makes the platform particularly relevant for research teams. The company reported 121.4 million daily active uniques in Q4 2025, up 19% year over year. However, scale also makes filtering, data quality, historical organization, and compliant collection essential.
The strongest strategy combines targeted source selection, structured extraction, historical storage, validation, analytics, and responsible use of publicly accessible information. Organizations should also review Reddit's current API and Developer Platform requirements before implementing a collection workflow.
Looking to turn Reddit conversations into structured market intelligence? Contact Real Data API to discuss a scalable, research-focused data collection solution!
FAQs
1. What is a Reddit Scraper used for?
A Reddit Scraper can collect permitted public posts, comments, timestamps, subreddit information, and engagement fields for market research, trend discovery, consumer analysis, and competitive intelligence.
2. What information can a Reddit Social Media Dataset contain?
A Reddit Social Media Dataset may contain publicly accessible post text, comments, subreddit names, timestamps, engagement metrics, URLs, topic labels, and other permitted research fields.
3. Is Reddit web scraping for market research useful?
Yes. Reddit web scraping for market research can reveal recurring customer questions, product opinions, emerging trends, competitor discussions, and category-level interests that complement conventional research methods.
4. How does Reddit real-time social media data help businesses?
Reddit real-time social media data can help teams monitor newly emerging discussions, detect changes in customer interests, identify fast-moving topics, and respond more quickly to market signals.
5. Can a Reddit data extraction API support large research projects?
A Reddit data extraction API can support structured retrieval workflows, but organizations should evaluate current Reddit access rules, authentication requirements, limits, and permitted use cases before implementation. Real Data API can help design an appropriate workflow.
Latest posts
How Trip.com travel dataset Helps Brands Track Hotel Prices, Reviews, Availability, and Competitor Trends
How Reddit Scraper Solutions Collect Public Data for Market Research and Competitive Analysis
How Wildberries Product Scraper Helps Track Prices, Sellers, and Product Availability
How Coupang Scraper Helps Monitor Products, Prices, Sellers, Reviews, and Market Changes


.png)


